Local Trillion-Parameter AI Workstations: How AMD and Nvidia Brought Frontier Compute to the Desk

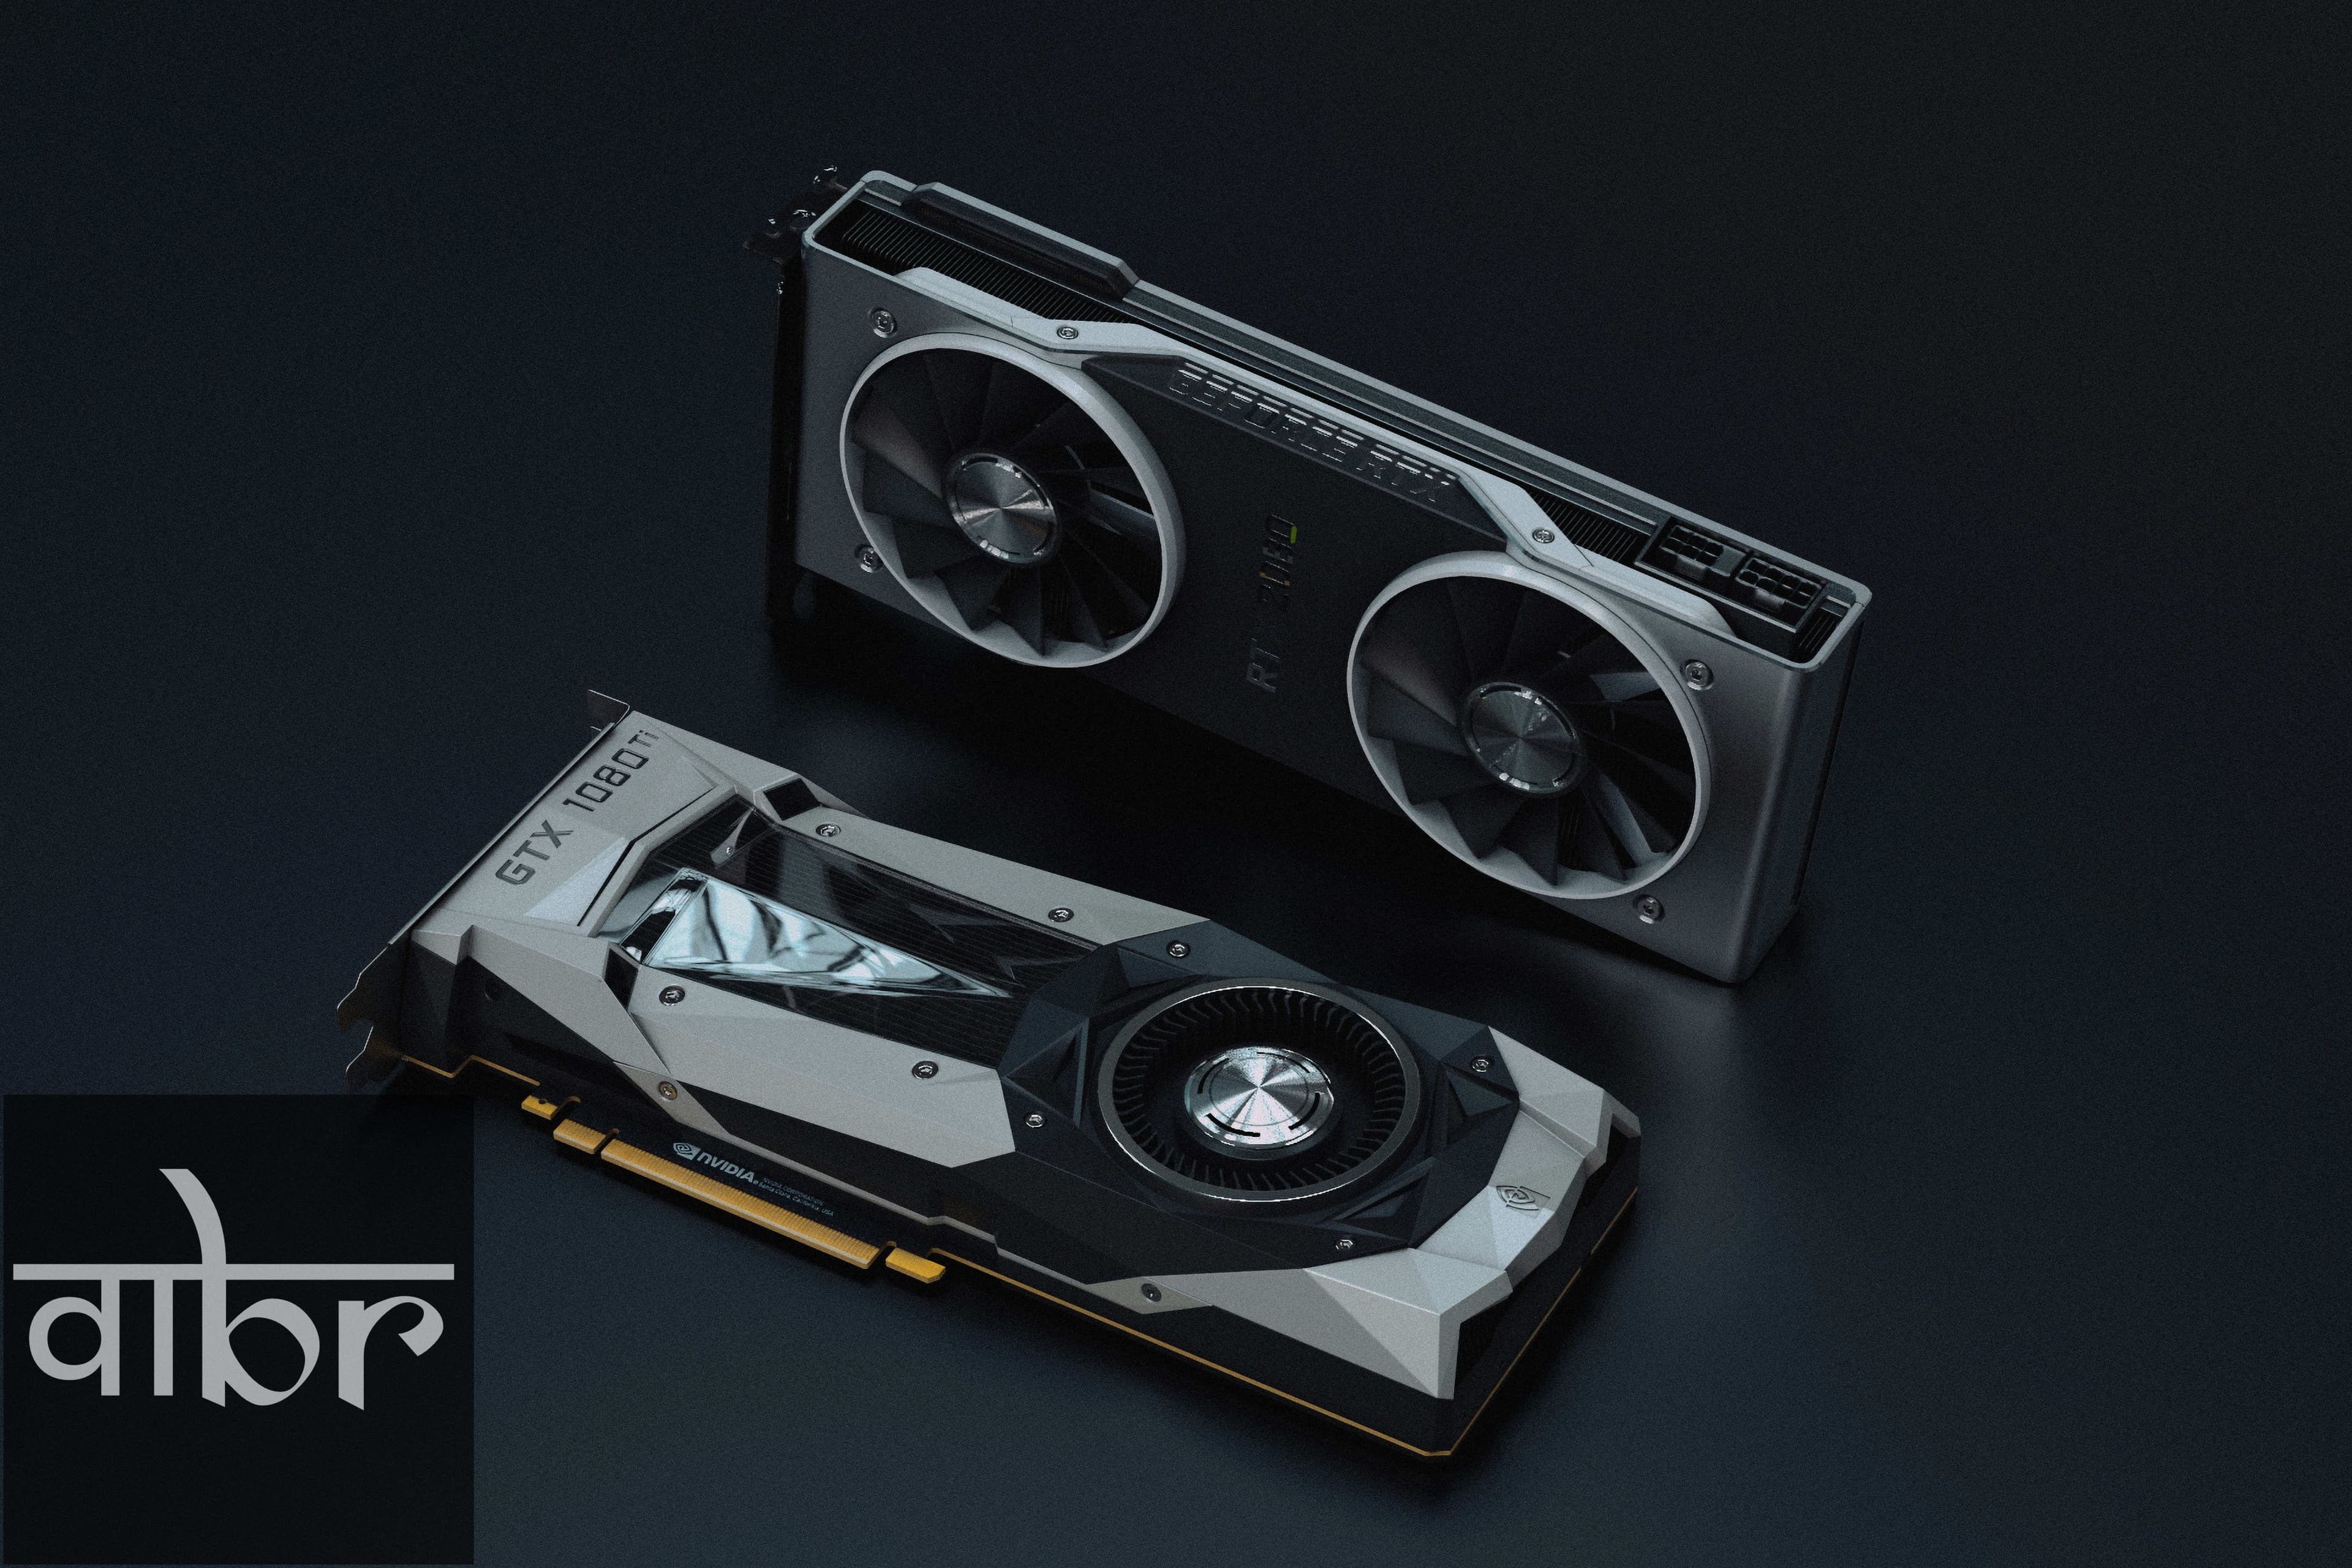
For years, engineering teams accepted a painful operational tax: if you wanted to fine-tune or run full-precision inference on frontier-scale machine learning models, your only option was a sprawling cloud instance. The friction was immediate. Data governance rules stalled deployment, variable cloud inference bills escalated rapidly, and network latency crippled iterative experimentation.
That balance of power has shifted toward extreme local workstations. Rapid engineering gains across interconnect fabrics, unified memory architecture, and workstation chassis design have made running massive model footprints locally practical for enterprise labs, independent research facilities, and regulated institutions.
The Memory Barrier: Why Trillion-Parameter Computing Is Unique
A trillion-parameter mixture-of-experts (MoE) or dense neural architecture requires immense working memory. Even when quantized down to 4-bit (INT4) or 8-bit (FP8) representations, storing active parameter weights, key-value (KV) caches, and activation contexts demands terabytes of low-latency addressable memory space.
Under legacy PCIe standards, distributing these weights across consumer or basic prosumer hardware caused severe interconnect bottlenecks. If GPU A had to wait on system RAM over congested pathways to sync attention heads with GPU B, token generation collapsed into single digits per second.
To eliminate this bottleneck, modern local super-workstations rely on three architectural pillars:
- High PCIe Lane Density: Modern workstation sockets provide up to 128 PCIe Gen 5 lanes, allowing four to eight dual-slot accelerators to communicate without lane bifurcation.
- Point-to-Point Bridge Topologies: Interconnect fabrics operate at multiple hundreds of gigabytes per second across cards, bypassing host CPU overhead entirely during tensor parallel calculations.
- Denser Local Framebuffers: Board partners have scaled individual accelerator VRAM capacities, allowing massive parameter offloading before spilling into system DDR5 memory.
Architecture Setup | Typical Usable GPU Memory | Target Model Size | Primary Workflow |
|---|---|---|---|
Dual Pro Accelerator | 96GB – 192GB | 70B – 120B (FP16/FP8) | Local Fine-Tuning & Quantized Inference |
Quad GPU Node | 192GB – 384GB | 200B – 400B (FP8) | Research Sandbox & Full Parameter LoRA |
Extreme Octa-GPU Node | Up to 576GB+ | 1T+ (Quantized / MoE Active) | Frontier Pre-deployment & Offline Inference |
AMD Threadripper and High-Density VRAM Fabrics
AMD's workstation push centers on memory footprint and raw throughput. By pairing workstation platforms like the Ryzen Threadripper PRO line with dense enterprise workstation GPUs—such as multi-card Radeon Pro configurations matching up to 576GB of pooled high-speed video memory—engineering teams can fit active MoE routing trees directly on-node.
Threadripper's core advantage lies in its host platform plumbing. An eight-channel DDR5 configuration supplies up to 2TB of high-bandwidth system memory, functioning as a secondary tier behind the primary GPU array. During parameter swapping in MoE setups, inactive expert blocks rotate between host system RAM and active VRAM smoothly, maintaining consistent token generation speeds.
For defense contractors, medical software teams, and financial modeling units bound by strict data compliance, this hardware density provides a self-contained compute vault. Proprietary intellectual property never leaves the local subnet.
Nvidia's Interconnect Ecosystem and Unified Execution
While AMD builds around massive PCIe density and raw memory addressing, Nvidia attacks the multi-GPU frontier through unified software scheduling and low-latency bridging. Through workstation-level runtime integrations and unified clustering frameworks, multi-accelerator desktop chassis function logically as a single execution block.
By leveraging peer-to-peer memory access over high-bandwidth links, workstation GPUs bypass standard OS-level memory locks. Instead of segmenting layers manually across hardware cards using fragile software sharding, unified runtimes split matrix multiplications natively across all available execution units.
Furthermore, high-efficiency FP4 and FP8 precision engines reduce memory footprints by half without degrading model output. This mathematical optimization effectively doubles the addressable parameter capacity of an existing physical workstation.
Real-World Bottlenecks: Power, Thermal, and Acoustic Constraints
Transitioning extreme AI compute from an air-conditioned server room to an office environment introduces real physical limits. Deploying four to eight enterprise accelerator boards alongside a 350W+ TDP workstation processor creates immediate site infrastructure demands:
- Electrical Dedicated Circuits: A four-to-eight accelerator workstation drawing heavy matrix workloads will pull between 1,800W and 3,200W from the wall. Standard 15A/120V household lines cannot handle this sustained load, requiring dedicated 20A or 240V industrial feeds.
- Thermodynamic Heat Load: Heat generation directly mirrors power consumption. A single dense workstation matches the thermal output of a residential space heater, necessitating active climate control or closed-loop liquid exhaust.
- Acoustic Engineering: High-RPM blower fans running at full duty cycle produce high decibel levels. Workstation system builders increasingly rely on liquid cooling blocks and external radiator bays to maintain tolerable noise levels in office spaces.
Frequently Asked Questions
Can a local workstation genuinely run a full 1-trillion parameter model?
Yes, with structural considerations. Dense 1-trillion parameter models run primarily under aggressive quantization (such as FP8, INT4, or mixed-precision MoE architectures). In Mixture-of-Experts architectures, only a fraction of the total parameters activate per token, allowing the system to run massive parameter graphs within 384GB to 576GB of aggregate memory.
What is the primary difference between server clusters and local AI workstations?
Server clusters scale out horizontally across multiple chassis using expensive high-speed network fabrics like InfiniBand. Local AI workstations scale up vertically inside a single motherboard and chassis, communicating directly over low-latency PCIe traces and bridge connectors. This eliminates networking configuration overhead and external hosting fees.
Is liquid cooling mandatory for multi-GPU local workstations?
For setups containing three or more high-wattage accelerators seated side-by-side, liquid cooling or high-velocity blower enclosures are strongly recommended. Traditional open-air card coolers simply recycle hot exhaust into adjacent boards, causing thermal throttling under sustained fine-tuning passes.
The Operational Verdict
Local trillion-parameter workstations are not mere replacements for budget hardware; they represent a fundamental change in development velocity. Retaining absolute control over model weights, running continuous benchmark evaluations without per-token charges, and guaranteeing data security makes local high-density hardware the standard foundation for modern AI engineering labs.
Varta Brief Editorial Desk
• Newsroom StaffDedicated to objective, deep, and fact-verified reporting across technology, science, world affairs, and modern markets.
Follow Varta Brief on Google
Add Varta Brief as a preferred source to see our verified stories and daily briefings in Google Top Stories and Discover.
Found this briefing insightful?
Share it with your colleagues and community.